

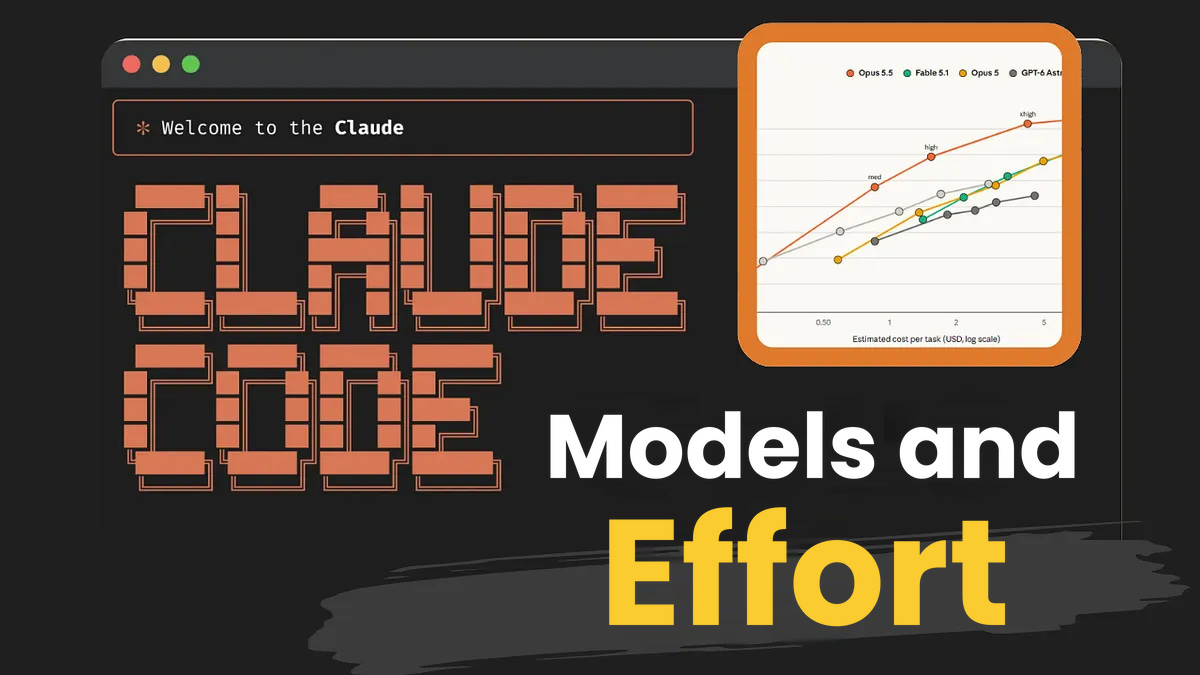
In Claude Code, /model picks the model and /effort sets the effort level, which controls how much work the model puts into each turn. Opus 5.5 and Sonnet 5.5 default to medium, and Fable 5.1 defaults to high. Below that is low, and above it are xhigh and max. Is the default enough? What does the extra money for higher effort actually buy? When should you switch models instead of raising the effort level? I ran five tasks to find out.
The tasks are small, the kind you’d normally hand to Claude Code: renaming a function, fixing a CSV import error, fixing a bug where month-end subscription renewals compute the wrong date, fixing flash-sale overselling, and speeding up a slow dedup function. Each task’s problem is written up in the repo’s ISSUE.md, essentially a ticket. For every task, I also wrote a test suite the model can’t see (called “hidden tests” below), which I run afterward to score the result.
